
🚀 Secret Studio AI: A Personal Project Turned Product
Secret Studio AI is a personal project turned product that allows users to create and share AI-generated content. The project was created by Fussy Pastor, who wanted to build a tool that would help him create AI-generated music and other content. The project has since evolved into a full-fledged product that allows users to create and share their own AI-generated content.
Key Points:
**
Personal Project Turned Product: Secret Studio AI was created as a personal project by Fussy Pastor, who wanted to build a tool that would help him create AI-generated music and other content.
AI-Generated Content: The project allows users to create and share AI-generated content, including music, videos, and other media.
User-Generated Content: The project allows users to create and share their own AI-generated content, giving them full control over the creative process.
🔗 Resources:
- Original post ↗
- Secret Studio AI
- Fussy Pastor
- Soundboostcom

Image
🤖 Drama 3: A Controllable TTS Model
Drama 3 is a controllable TTS model that allows users to describe the tone, pacing, and character of the generated speech in simple language. The model can also shift the voice mid-sentence, generate a multi-character scene, or fix only a single word.
Key Points:
**
Controllable TTS Model: Drama 3 is a controllable TTS model that allows users to describe the tone, pacing, and character of the generated speech in simple language.
Shift in Voice Mid-Sentence: The model can shift the voice mid-sentence, allowing for more nuanced and expressive speech.
Multi-Character Scene Generation: The model can generate a multi-character scene, allowing for more complex and engaging speech.
🔗 Resources:
- Original post ↗
- FishAudio
- Drama 3
Image
📢 Audio Processing
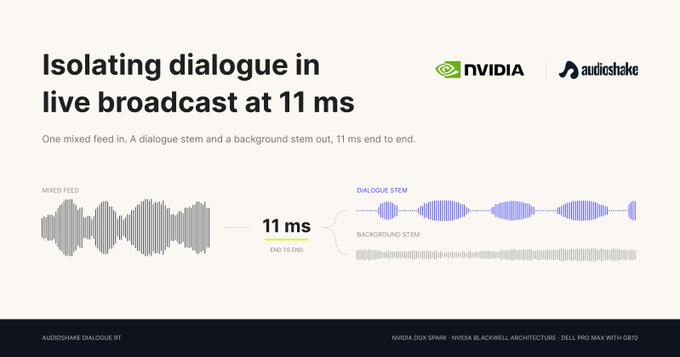
Isolating Dialogue in Live Broadcast at 11 ms with AudioShake on NVIDIA DGX Spark
AudioShake has achieved a breakthrough in isolating dialogue in live broadcast, with a processing time of just 11 ms. This is made possible by the use of NVIDIA DGX Spark and Blackwell architecture GPUs.
Key Points:
**
11 ms Processing Time: AudioShake has achieved a processing time of just 11 ms, making it possible to isolate dialogue in live broadcast in real-time.
NVIDIA DGX Spark and Blackwell Architecture GPUs: The use of NVIDIA DGX Spark and Blackwell architecture GPUs has enabled this breakthrough in audio processing.
Real-Time Dialogue Isolation: The technology can isolate dialogue in live broadcast in real-time, making it possible to create more engaging and interactive audio experiences.
🔗 Resources:
- Original post ↗
- AudioShakeAI
- NVIDIA DGX Spark
- Blackwell architecture GPUs
Image
🚀 FLUX 3 Action: An Open-Weight 7B World-Action Model
FLUX 3 Action is an open-weight 7B world-action model that has achieved SOTA performance and efficiency on various leaderboards, including RoboLab. The model is open-weight, meaning that both backbone and embodiment-specific finetunes are open weight.
Key Points:
**
Open-Weight 7B World-Action Model: FLUX 3 Action is an open-weight 7B world-action model that has achieved SOTA performance and efficiency on various leaderboards.
SOTA Performance and Efficiency: The model has achieved SOTA performance and efficiency on various leaderboards, including RoboLab.
Open-Weight Backbone and Embodiment-Specific Finetunes: The model is open-weight, meaning that both backbone and embodiment-specific finetunes are open weight.
🔗 Resources:
- Original post ↗
- Laion AI
- RoboLab
- FLUX 3 Action

Image
🎧 Armin van Buuren on Emotion and Creativity
Armin van Buuren shares how emotion shapes his creative process and the connection he wants his music to create. In the latest Off the Record, he discusses the importance of feeling and connection in his music.
Key Points:
**
Emotion and Creativity: Armin van Buuren shares how emotion shapes his creative process and the importance of feeling and connection in his music.
Connection and Engagement: He discusses the connection he wants his music to create with his audience and the importance of engagement in his creative process.
Off the Record: The interview is part of the Off the Record series, which explores the creative process and inspirations of various artists.
🔗 Resources:
- Original post ↗
- Moises AI
- Armin van Buuren
- Off the Record

Image
📢 Live Podcast Platform with AI Hosts
A live podcast platform with AI hosts has been built using Gemini 3.8 Flash TTS, Gemini 3.5 Transcribe Live, and Agora RTC. The platform allows for a more immersive and engaging listening experience, with AI hosts that can adapt to the conversation.
Key Points:
**
Live Podcast Platform with AI Hosts: The platform allows for a live podcast experience with AI hosts that can adapt to the conversation.
Gemini 3.8 Flash TTS and Gemini 3.5 Transcribe Live: The platform uses Gemini 3.8 Flash TTS and Gemini 3.5 Transcribe Live to generate and transcribe the conversation in real-time.
Agora RTC: The platform uses Agora RTC to enable real-time communication and collaboration.
🔗 Resources:
- Original post ↗
- AgoraIO
- Gemini 3.8 Flash TTS
- Gemini 3.5 Transcribe Live

Image
🎶 Glitchstep and Metal Music
Fussy Pastor has been experimenting with blending glitchstep into metal music, with promising results. The music is created using Soundboostcom's MVG.
Key Points:
**
Glitchstep and Metal Music: Fussy Pastor has been experimenting with blending glitchstep into metal music, creating a unique and engaging sound.
Soundboostcom's MVG: The music is created using Soundboostcom's MVG, which allows for a high degree of creative control.
Unique Sound: The resulting music is a unique blend of glitchstep and metal, with a high degree of energy and complexity.
🔗 Resources:
- Original post ↗
- Soundboostcom
- Fussy Pastor
- MVG

Image
📢 Voice AI is Not Only Real-Time
Voice AI is not only used for real-time applications, but also for processing and analyzing years of call center recordings, medical conversations, and other audio data. This data can be used to train and improve voice AI models.
Key Points:
**
Voice AI is Not Only Real-Time: Voice AI is not only used for real-time applications, but also for processing and analyzing years of audio data.
Call Center Recordings and Medical Conversations: The data can be used to train and improve voice AI models, with applications in call center automation and medical diagnosis.
Years of Audio Data: The data can be used to analyze and improve voice AI models, with applications in various industries.
🔗 Resources:
- Original post ↗
- Soniox AI
- Voice AI

Image
🎧 AI Music Video Generation
Fussy Pastor has used Soundboostcom's AI Music Video generation service to create a music video for a new song. The video is created using AI algorithms and can be customized to fit the artist's style.
Key Points:
**
AI Music Video Generation: Soundboostcom's AI Music Video generation service allows artists to create music videos using AI algorithms.
Customization: The video can be customized to fit the artist's style, with options for color, lighting, and special effects.
AI Algorithms: The video is created using AI algorithms, which can be trained on a variety of data sources.
🔗 Resources:
- Original post ↗
- Soundboostcom
- Fussy Pastor
- AI Music Video Generation

Image
🤖 Gemini 3.8 Flash TTS and Flash-Lite TTS Models
Google's Gemini 3.8 Flash TTS and Flash-Lite TTS models address a persistent limitation in voice AI by giving developers finer control over how generated speech sounds and adapts throughout a conversation.
Key Points:
**
Gemini 3.8 Flash TTS and Flash-Lite TTS Models: The models address a persistent limitation in voice AI by giving developers finer control over how generated speech sounds and adapts throughout a conversation.
Finer Control: The models provide finer control over the tone, pacing, and character of the generated speech.
Adaptability: The models can adapt to the conversation, allowing for more natural and engaging speech.
🔗 Resources:
- Original post ↗
- AgoraIO
- Gemini 3.8 Flash TTS
- Flash-Lite TTS
Image
